Vidova
Speech cleanup
上传一段你讲话的录像。Vidova 会剪掉“嗯”、说错重来、重复的句子和长时间停顿,并按你选择的节奏保留句间间隔。
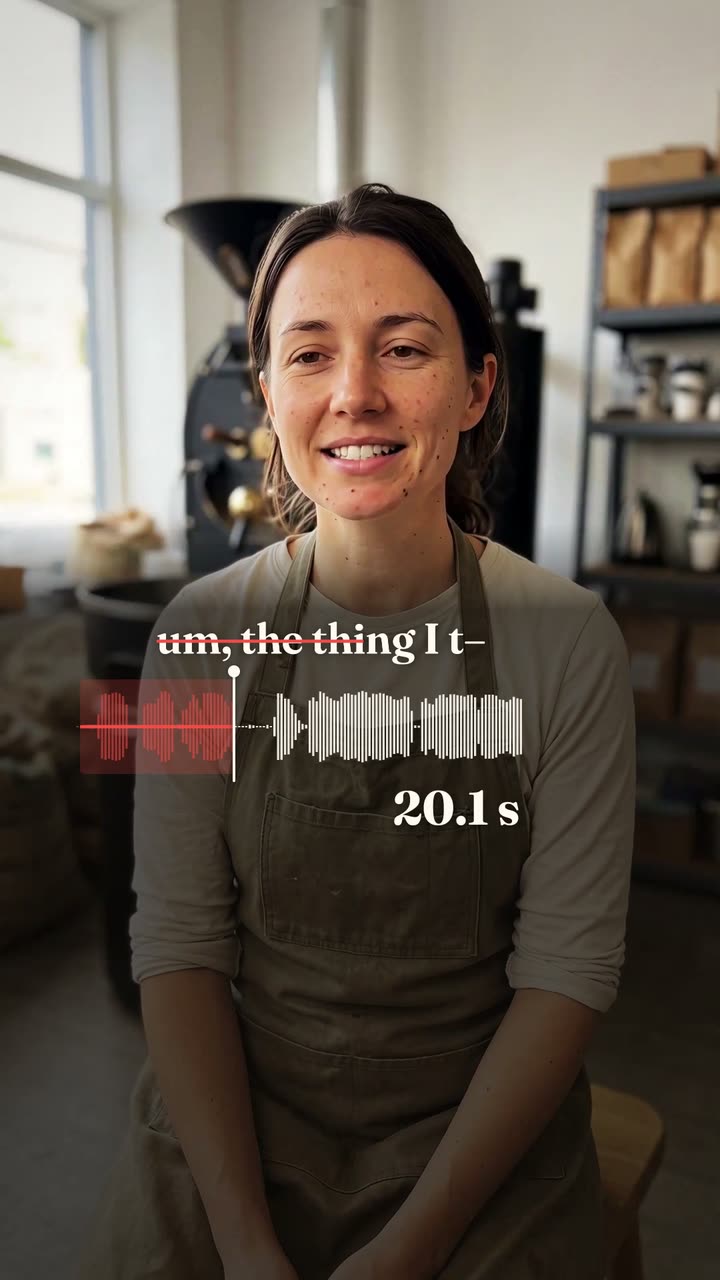
你的录像*你对着镜头讲话的视频。Vidova 会保留你说的内容,只剪掉口误和较长的停顿。
节奏*每句话之间保留多少空白。预览会在同一段素材上展示每种节奏。
Vidova 将会做什么
Clean up my talking-head video. Transcribe what I say, then cut out the filler words (um, uh, like, you know), false starts, repeated starts of a line and long pauses, so it plays as one clean take. Make every cut in a pause between words, never inside a word, with a 10 ms sound fade on each cut. Where a filler runs into the next word with no pause, move the cut to the nearest real pause. Keep my words in the order I say them, keep my footage and my sound as they are, and end on my last full sentence. Pace: Natural. Leave about 0.3 s of quiet between lines, as I pause when I talk normally.